kottke.org posts about RSS
Hello, good afternoon! As I mentioned a few weeks ago, I have a bunch of new stuff for KDO in the pipeline. I’ve been focused on backend infrastructure recently to make my life (hopefully) easier and have gotten that to a place of “useful enough to test out to find all the bugs & irritations”. So onto some things that you folks can actually use.
When I launched the KDO Rolodex last July, it was a simple list of five recommended sites on the front page of the site. You could refresh to see more sites, but you couldn’t see the whole list all at once. Fun, but lots of room for improvement.
Over the weekend, I launched the full list of sites (186 at the moment) for your perusal. Any visitor to the site can see the sites & people I read to help make KDO. I’ve written before about why this is important to me:
I love linking out to other sites. The strength of the open web is in its many connections between nodes…the more, the better. Links are the whole goddamned point of the web! I want to send people away from kottke.org to learn something new or have a chuckle and then come back the next day for more. The goal is connection, knowledge, and sharing — I proudly have no competitors in this endeavor, only collaborators.
I loved seeing the whole list. So I kept pushing made something I’ve had on my todo list for awhile: I turned the Rolodex into a tiny RSS feed reader. Which I love even more. The feed reader feature is a bit rough around the edges, so I’m making available only to members while we beta test it. Here’s what it looks like:
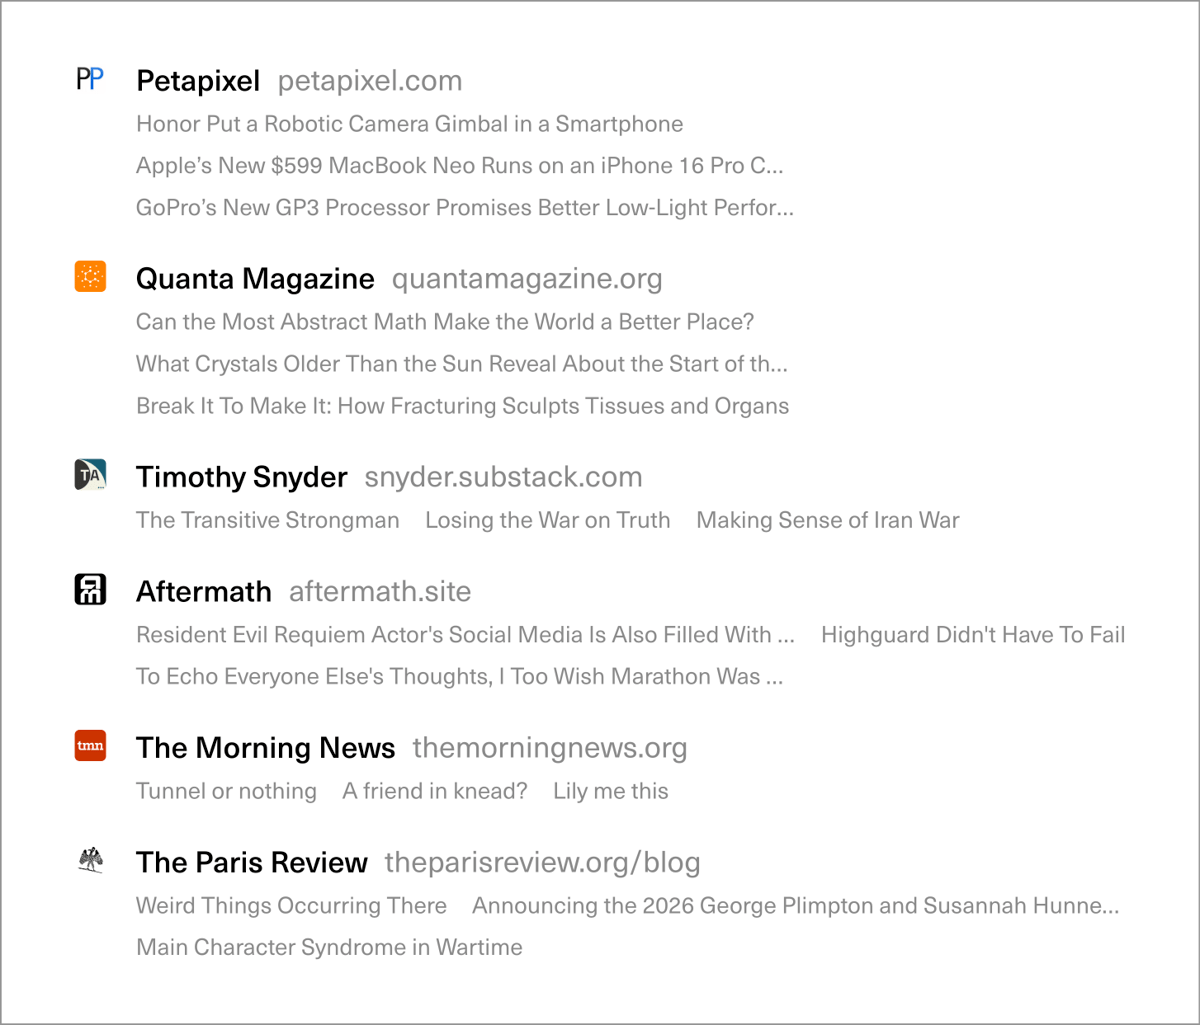
The three latest posts from each site or person are listed below their name; clicking on a post title will open the post in a new tab. You can obviously click on the name of the site/person to open that in a new tab too. Sites are sorted by most recently updated (this is true of the public listing as well). If you’re a member, please check it out and kick the tires.
For the curious, some details about the implementation. I use Feedbin as my feed reader and they have a pretty good API. So I built a sync system that adds the URLs of the sites in the Rolodex (if they have associated feeds) to Feedbin and tags them with “Rolodex”. Once the feeds are associated with sites, I can just retrieve new entries from those Rolodex-tagged feeds (every 30 min currently). There are a few sites causing problems — for instance, Beehiiv newsletters don’t appear to have RSS feeds by default?1 — and there are some other bugs, but I’m working on it. I’m not including posts from social sites (Bluesky, Mastodon) for now because that’s another level of velocity.
But like I said, I am loving this casual wee feed reader so far. No read/unread statuses, no counts, no folders, no pressure to catch up, no 3-pane view. I’d say 90-95% of the sites on the list work fine — and it doesn’t need to be 100%. Try it out, lemme know what you think.
Thanks to KDO members for helping to fund new features like this. If you’d like to help support the site, check out your membership options here. ✌️
Earlier this week, Dave Winer (the inventor of RSS and lots of other notable software, and one of the earliest bloggers) made a podcast for me. He posted it publicly, so it wasn’t sealed like a letter, but it was addressed to me and responding to something I wrote on Threads. I don’t think I’ve ever been the personal addressee of a podcast before: like an @-reply, but in audio.
For some reason, it reminded me of the poet Frank O’Hara’s “Personism” manifesto:
[Personism] was founded by me after lunch with LeRoi Jones on August 27, 1959, a day in which I was in love with someone (not Roi, by the way, a blond). I went back to work and wrote a poem for this person. While I was writing it I was realizing that if I wanted to I could use the telephone instead of writing the poem, and so Personism was born. It’s a very exciting movement which will undoubtedly have lots of adherents. It puts the poem squarely between the poet and the person, Lucky Pierre style, and the poem is correspondingly gratified. The poem is at last between two persons instead of two pages. In all modesty, I confess that it may be the death of literature as we know it.
But this is a digression. The ideas Dave is talking about in this podcast are serious (even if he is laughing a lot), and he spells them out in text at a site called Textcasting.org. Here’s the philosophy:
- The goal is interop between social media apps and the features writers need.
- What we’re doing: Moving documents between networked apps. We need a set of common features in order for it to work.
- The features are motivated by the needs of writers. Not by programmers or social media company execs.
It’s a proposal to build, using technologies we already have and understand very well, a very simple social media protocol that is completely agnostic about what editor you use to write your posts and what viewer you choose to read it. Writer/authors would have more control over styling, links, media enclosures, etc., and readers would have more control over how and where they consume it. It’s decentralized social media, but without the need to peer through ActivityPub or anybody else’s API and squeeze our toothpaste through its tubes.
Dave asked me to respond to his podcast, and while I thought about making an audio response, a blog post is more my metier.
If this is going to work, I think there are at least four problems we’d have to solve:
- Everyday users need a default writer and reader, preferably in the same place. It would be wonderful to be able to bring your own tools to bear and plug into the endpoints and have it just work. But nobody should need to fish around for that stuff. The defaults should be just opinionated enough (for instance, I like the Mastodon client Ivory, built on the ashes of TweetBot) that people feel like they’re getting a slick, finished UI and UX experience. That’s why people are gravitating to Threads: Meta knows how to put one together. But that’s not rebuilding the electrical grid from scratch. We know how to do that too.
- We need user and content discovery. We have to be able to find each other. And that’s what a lot of the heavy lifting of these other platforms is devoted to: to find people and things you didn’t know you were looking for. Again, this feels like a solvable problem.
- We need metrics. Most writers work for publishers, and publishers want to know whether their content is reaching people. It’s tempting to load this up with a lot of cruft, but impressions, clicks, reposts, quote posts, etc. is doable without a ton of advertising nonsense. Social media companies figured this out, but bloggers did too, a lot earlier.
- We need moderation. A wide-open social network becomes a highly abusive social network fast in 2023. And nobody who isn’t a Nazi wants to hang out at a Nazi bar. So we need tools to block and flag and maybe even ban people who use the platform to spam each other, impersonate real people, and abuse other people on the platform. In the now-seminal “Welcome to Hell, Elon,” Nilay Patel correctly identified content moderation as Twitter’s actual product: it’s what Twitter-the-company added to Twitter-the-protocol. We don’t necessarily need a Twitter-sized overhead, or a complex system of federated moderators, but it’s going to be a problem, so we’d need tools to address it.
But in terms of philosophy and vision, I’m all for it. RSS remains incredibly vital to what I do, and its potential as both a reading AND a writing platform remains untapped. You can write using your own tool and broadcast it everywhere. And Dave’s right: this worked for podcasts (the phrase “anywhere you get your podcasts!” is a great advertisement for interoperability breaking any single platform’s dominance), it worked for blogs, and it can work for this strange multimodal thing we’ve created called social media. It worked for the world wide web! And I will be ride or die for the open web until my life comes to an end.
Now we just need to work together to make it happen. And I confess: my tools are limited here. I can’t (really) code, I can’t (really) design, I can’t build a moderation feature. I can evangelize, I can strategize, and I can write. But I can do those things (in all modesty) very, very well.
So let’s do this thing. Why not? Twitter is dying, and Facebook is fading. None of the replacements have eaten their lunch yet. Why not make a swing for the open web? Why not try?
Writing for Wired, Matt Homan Mat Honan on Betaworks’ race to build a replacement for Google Reader in just 90 days. If you are interested in a 35,000-ft view on how Web-based software is built, read this.
McLaughlin saw a blog post in the Fall of 2012 speculating that Google Reader, choked of resources, was shutting down. He sent a teasing note to a friend at Google offering to “take it off their hands.” To his surprise, he got a serious reply. Google, his friend replied, had concluded that it couldn’t sell the name, user data, or code base (which would only run on their servers) and so there was nothing to actually buy.
The following February, McLaughlin, now full-time at Digg, bumped into this same pal at a TED conference. The friend warned him to act fast if he really did want to develop a Reader. “He said ‘I’m not telling you anything, but we’re not going to keep this thing around forever and maybe you want to have something ready by the end of the year.”
But instead of year’s end Google announced plans to shutter Google Reader on July 1. That same night, Digg put up a blog post announcing that it was going to build a replacement. The Internet went crazy.
Loved seeing ye olde kottke.org represented in the Digg Reader mockups, and I’m looking forward to checking out the service when it launches.
You may have heard by now that Google is shutting down Google Reader, their RSS reading service. It’ll be gone by July 4. Fortunately you can export your subscriptions and use another service…here are some suggestions from Matt Haughey and Gizmodo. Or you can wait for Digg’s reader.
If you want to forego RSS readers altogether but still want to keep up with kottke.org without having to visit the site regularly, try following kottke.org on Twitter, Facebook, or Tumblr.
After using Newsfire for many years, I recently switched to Google Reader for reading RSS feeds. I’m not sold on Reader yet, but I’m going to give it a solid chance. After poking around online and leaning on my Twitter pals (thanks!), I’ve come up with a system that seems to work for me on OS X, at least for extensive testing purposes.
1. Download Fluid. Fluid creates standalone desktop apps out of web pages. After installing, paste in Google Reader’s URL, name the app “Google Reader”, and use a pretty icon (or two). Launch your new app…voila, Google Reader as a standalone app.
2. Install the Helvetireader theme for Google Reader. To do this, go to the Scripts menu in your Google Reader Fluid app (it’s the scroll graphic to the left of the Window menu) and select “New UserScript”. Name your script “helvetireader”. At the prompt, select “Override” and then close that window. From the Script menu, select “Open Userscripts Folder”…this will open the ~/Library/Application Support/Fluid/SSB/Google Reader/Userscripts folder in the Finder. Download the Helvetireader UserScript from the web site and save it over the file of the same name in that Userscripts folder. Go back to the GR Fluid app and select “Reload All Userscripts” from the scripts menu. You should be seeing something that looks like this.
3. Make Google Reader your default RSS reader. In Safari, go to Preferences / RSS / Default RSS Reader, choose “Select…” and find the GR Fluid app in your Applications folder. In Firefox, go to Preferences / Applications, scroll down to Web Feed, choose “Use other…” and find the GR Fluid app in your Applications folder. Now clicking on RSS icons and feeds in these browsers will open an “add this feed” page in the GR Fluid app.
If you don’t want to go the Fluid route, you can also use Reader Notifier to let you set Google Reader as your default RSS reader in Safari.
Week-long exclusive sponsorships of kottke.org’s RSS feed are available through the end of March.
In sponsoring the feed, you get the chance to promote your company or product in a short post that will appear in the feed. A sponsor “thank you” note will also be posted to the front page of the site. Your message will reach an estimated 110,000+ RSS subscribers.
If you’re interested, check out the sponsorship page for details and get in touch. Thanks!
Hear ye! I’m trying something new on kottke.org. Sponsorships of kottke.org’s RSS feed are now available on a weekly basis. Sponsorships are exclusive and begin next week. If you’re interested, check out the sponsorship page for details and get in touch.
P.S. The feed sponsorship idea was borrowed from John Gruber’s Daring Fireball. I’d urge you to head on over to check out his sponsorship opportunities, but the DF feed is fully booked through the end of the year. (!!)
P.S.2. Advertising on the site proper continues to be handled expertly by The Deck. If you’d like to advertise on the site, read up on your options there.
I’m moving some things around on the backend of the site so those of you reading kottke.org in RSS may have noticed some duplicate items. Sorry about that…it’s a one time occurance and was mostly unavoidable.
Warning, RSSoterica and kottke.org sausage-making to follow. Matt Wood has a post up on 43Folders about how he groups his RSS feeds in Google Reader for easier reading. I use pretty much the same system as Matt, but with a few more folders. I have several folders for reading long-form blogs:
Always
Often
Sometimes
Pending
Food and Drink
Frippery
Infoglut
Always, Often, and Sometimes are self-explanatory. The Pending folder is for blogs that I’m trying out, Frippery is stuff that is non-kottke.org-related to be read during non-work hours (ha!), and the Infoglut folder contains a bunch of blogs that have a low signal-to-noise ratio and are too high volume to keep up with unless everything else is read (any multi-author pro blogs that I read (not many) are in here). For organizing non-long-form blogs, I use these folders:
Links
Yummy
Photos
Tumble
Links contains link blogs, Yummy has a bunch of stuff from del.icio.us, Photos are photoblogs, and Tumble contains tumblelogs, FFFFOUND!, and other Randomly Curated Other People’s Images White Background Sites. And then for news, I have an NY Times folder, a Sci/Tech News folder, and a Keywords folder for Google News keyword searches.
All this folder business might seem overcomplicated, but I find that grouping feeds by mode helps greatly. And by mode, I mean when I’m reading link blogs, that’s a different style than reading/skimming long-form blogs in the Always folder. Posts from link blogs usually take a few seconds to read/evaluate/discard while the Always folder posts take longer. If they were all lumped together, I couldn’t get through them as quickly and thoroughly as I can separately. A juggling analogy will help — Wait! Don’t leave, I’m almost done! — it’s easier to juggle balls or clubs or knives than it is to juggle balls, knives, and clubs at the same time…same thing with different kinds of blog posts.
- I’m kind of amazed that this thing lives up to the expectations I had for it. It’s an amazing device.
- To read RSS, just put a feed address into Safari and Apple redirects it through their iPhone feed reader. But it’s very much of an a la carte thing, one feed at a time. What’s needed is a proper newsreader with its own icon on home screen. Workarounds for now: Google Reader looks nice or you could make a collective feed that combines all the feeds you want to read on your iPhone and use that with the iPhone feed reader (Meg’s idea).
- I skipped the index finger and am right into the two thumb typing. With the software correction, it’s surprisingly easy. Or maybe I just have small lady thumbs.
- After fiddling with it for an hour, I know how to work the iPhone better than the Nokia I had for the past 2 years, even though the Nokia has far fewer capabilities.
- I could use the Google Maps app forever.
- When I go back to using my Macbook Pro, I want to fling stuff around the screen like on the iPhone. It’s an addictive way to interface with information.
- Finding Nemo looked really nice on the widescreen display.
- You can pinch and expand with two thumbs instead of your thumb and index finger.
- The camera is not what you would call great, but it’s as good as my old phone’s, which is about all I want out of it. The lack of video is a bit of a bummer.
- I Twittered from on line at the AT&T store that the line was moving slowly because they were doing in-store credit checks and contract sign-ups, contrary to what everyone had been told by Apple beforehand. That was not the case. They were just being super careful with everything…each phone and the bag that it went into had a bar code on it and they were scanning everything and running phones from the back of the store one at a time. The staff was helpful and courteous and it was a very smooth transaction, all things considered. I was on line for 2 hours before the store opened and then another 2 hours waiting to get into the store.
- The alert options (ringtones, vibrate options, messaging alerts, etc.) aren’t as fine-grained as I would like, but they’ll do for now.
- I have not tried the internet stuff on anything but my home WiFi network, so I don’t know about the EDGE network speed. Will try it out and about later.
- The Google Maps display shows the subway stops but not the full system map. Workaround: stick a JPG of the subway map in your iPhoto library and sync it up to the iPhone. Voila, zoomable, dragable NYC subway map.
- Wasn’t it only a year or two ago that everyone was oohing and aahing over Jeff Han’s touchscreen demos? And now there’s a mass-produced device that does similar stuff that fits it your pocket. We’re living in the future, folks…the iPhone is the hovercar we’ve all been waiting for.
Update:
- The iPhone is the first iPod with a speaker. Which means that in addition to using it as a speakerphone, you can listen to music, podcasts, YouTube videos, and movies without earphones. Which might seem a bit “eh”, but won’t once you have 15 people gathered around watching and listening to that funny bit from last night’s Colbert Report. You know, the Social.
- I’m getting my mail right off my server with IMAP, so when it gets to the phone, it hasn’t gone through Mail.app’s junk filters…which basically means that mail on the iPhone is useless for me. In the near future, I’m going to set things up to route through GMail prior to the phone to near-eliminate the spam.
- Tried the EDGE network while I was out and about. Seemed pretty speedy to me, not noticeably slower than my WiFi at home…which may say more about Time Warner’s cable modem speeds than EDGE.
- BTW, all of these first impressions are just that. You can’t judge a device or an interface without using it day to day for awhile. I’m curious to see how I and others are still liking the phone in two weeks.
- Everytime I connect the iPhone to my computer, Aperture launches. Do not want.
Made some long overdue changes to the sidebar on the front page, including an even longer overdue update of the “sites I’ve enjoyed recently”. I used to use that list for my daily browse but it fell into decay when I started reading sites in RSS. Now the list is a random sampling of sites from the current reading list in my newsreader. If things look a little weird, you may need to refresh the stylesheet (do a Shift-reload on the home page).
- Pruning the list of RSS feeds I follow.
- Digging.
- Writing about hoes.
- Keeping deer out of the
s.
- Growing my traffic.
- Worrying about bees.
- (Com)posting links?
- Weeding out spam from comment threads.
- ^s.
- There’s never enough thyme.
- Wondering about the weather.
The New Yorker redesign just went live. Not sure if I like it yet, but I don’t not like it. Some quick notes after 15 minutes of kicking the tires, starting with the ugly and proceeding from there:
- Only some of the old article URLs seem to work, which majorly sucks. This one from 2002 doesn’t work and neither does this one from late 2005. This David Sedaris piece from 9/2006 does. kottke.org has links to the New Yorker going back to mid-2001…I’d be more than happy to supply them so some proper rewrite rules can be constructed. I’d say that more than 70% of the 200+ links from kottke.org to the New Yorker site are dead…to say nothing of all the links in Google, Yahoo, and 5 million other blogs. Not good.
- The full text of at least one article (Stacy Schiff’s article on Wikipedia) has been pulled from the site and has been replaced by an abstract of the article and the following notice:
The New Yorker’s archives are not yet fully available online. The full text of all articles published before May, 2006, can be found in “The Complete New Yorker,” which is available for purchase on DVD and hard drive.
Not sure if this is the only case or if the all longer articles from before a certain date have been pulled offline. This also is not good.
- They still default to splitting up their article into multiple pages, but luckily you can hack the URL by appending “?currentPage=all” to get the whole article on one page, like so. Would be nice if that functionality was exposed.
- The first thing I looked for was the table of contents for the most recent issue because that’s, by far, the page I most use on the site (it’s the defacto “what’s new” page). Took me about a minute to find the link…it’s hidden in small text on the right-hand side of the site.
- There are several RSS options, but there’s no RSS autodiscovery going on. That’s an easy fix. The main feed validates but with a few warnings. The bigger problem is that the feed only shows the last 10 items, which isn’t even enough to cover an entire new issue’s worth of stories and online-only extras.
- A New Yorker timeline. Is this new?
- Listing of blogs by New Yorker contributors, including Gladwell, SFJ, and Alex Ross.
- Some odd spacing issues and other tiny bugs here and there. The default font size and line spacing make the articles a little hard to read…just a bit more line spacing would be great. And maybe default to the medium size font instead of the small. A little rough around the edges is all.
- The front page doesn’t validate as XHTML 1.0 Transitional. But the errors are pretty minor…
instead of
, not using the proper entity for the ampersand, uppercase anchor tags and the like.
- All articles include the stardard suite of article tools: change the font size, print, email to a friend, and links to Digg, del.icio.us, & Reddit. Each article is also accompanied by a list of keywords which function more or less like tags.
- Overall, the look of the site is nice and clean with ample white space where you need it. The site seems well thought out, all in all. A definite improvement over the old site.
Thanks to Neil for the heads up on the new site.
Older posts

Socials & More